TikTok Niche Classification: How Consistent Topic Signals Help Systems Understand Content
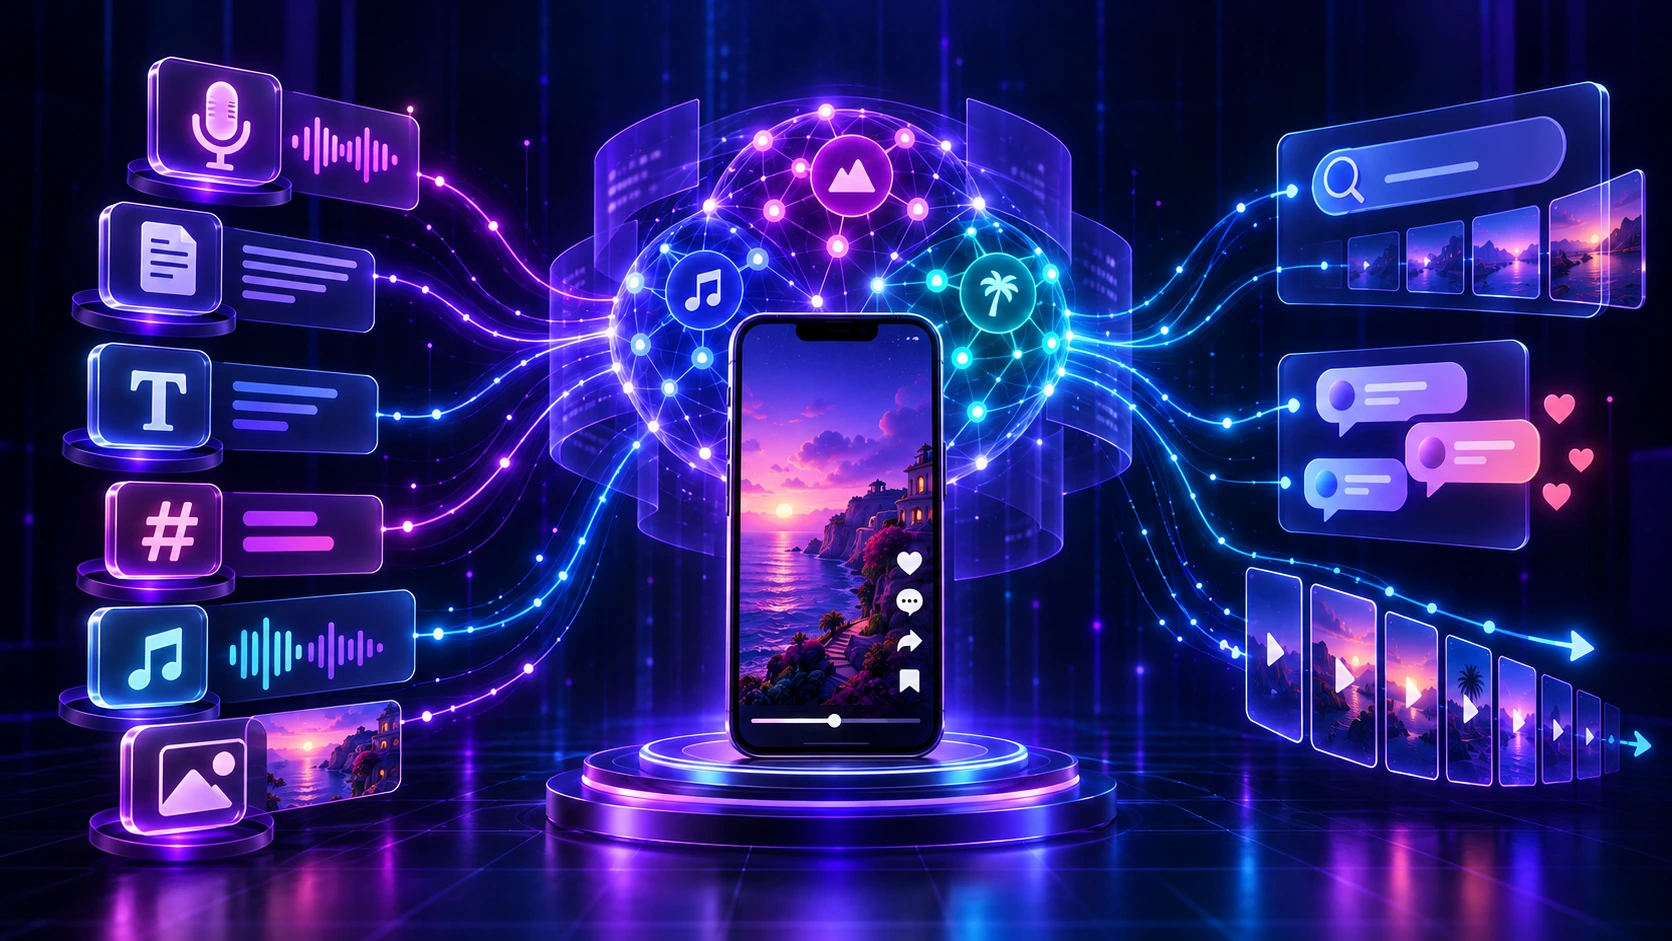
TikTok niche classification is best treated as an evidence problem, not a creator-visible score. A video communicates its subject through its actual content, spoken language, on-screen text, caption, hashtags, sound and surrounding context. Search discovery, comments and engagement can then provide supporting evidence about how people found or interpreted it. None of these observations reveals a hidden label, weight or permanent niche assignment.
The practical goal is semantic clarity: make the main entity, attribute and audience need consistent enough that a viewer—or a system processing several kinds of information—has less ambiguity about the video’s subject. That does not mean repeating one keyword everywhere. It means the evidence tells a coherent story.
What Are TikTok Topic Classification Signals?
Topic classification signals is an analytical term for observable evidence that may help describe what TikTok content is about. TikTok does not publicly provide creators with a universal niche score or a complete list of internal topic labels. Its public explanation instead says recommendation systems consider broad categories of information, including user interactions, content information and user information. For the For You feed, TikTok lists sounds and hashtags among content information; for Search, it says content-query match, hashtags and sound may influence results.[1]
That documentation supports a limited claim: content information and viewer activity can matter in recommendation and discovery contexts. It does not show the complete classification pipeline, confirm a fixed hierarchy of topic signals or disclose why one particular video was distributed.
A sound, caption or comment should therefore be recorded as evidence with a source and limitation. A creator can observe the published video, its metadata and available analytics. The creator cannot ordinarily observe internal embeddings, candidate sets, model confidence, learned weights or per-viewer ranking decisions.
Six Evidence Layers That Should Remain Separate
- Creator-provided content evidence: the caption, hashtags, selected sound, account context and series labels supplied around the post.
- Content-derived semantic evidence: spoken words, meaningful on-screen text, visible objects, actions, scenes and the demonstrated outcome.
- Viewer and audience-response evidence: comments, watches, skips, likes, shares, saves and other available actions.
- Search and discovery evidence: surfaced queries, Search traffic and other traffic-source context where the account provides it.
- Distribution outcomes: views attributed to For You, Search, Following, Profile, Sound or another available source.
- Analyst interpretation: the explanation proposed after reviewing the evidence, comparison group, confounders and uncertainty.
Evidence in one layer does not automatically establish what happened in another. A caption can declare the intended topic without proving that viewers understood it. Recurring comments can show an audience interpretation without proving TikTok used the same interpretation. For You views are a distribution outcome, not proof that a particular keyword, hashtag or topic label caused distribution.
How TikTok Content Communicates Its Subject
Videos are multimodal: meaning can appear in visuals, motion, speech, music and text at the same time. Research on video classification has shown that visual, audio and textual features can be combined to classify videos, but that research does not document TikTok’s current models or weights.[3] It simply offers a useful reason to examine several evidence types instead of treating a caption or hashtag as the whole subject.
Primary Subject and Supporting Attributes
Start by expressing the intended topic in a simple relationship:
- Primary entity: the person, object, process, product, place or concept at the center of the video.
- Primary attribute or question: what the video explains, compares, demonstrates or asks about that entity.
- Audience need: the problem, curiosity or decision the video is intended to serve.
“Coffee” is too broad to evaluate well. “How to reduce bitterness in cold brew” identifies an entity, an attribute and a practical need. Supporting evidence might include grind size, steeping time and dilution. Those details strengthen the main topic when they serve the same question. A long detour into espresso machines introduces a competing subject.
Visual Objects, Scenes and On-Screen Text
Visible subject matter can provide strong descriptive evidence. A repair tutorial may show the device, damaged part, tool and completed fix. A recipe may show ingredients and sequential actions. Record what is materially visible rather than what the creator assumes viewers will infer.
On-screen text can name an entity, step or outcome, especially when the visual alone is ambiguous. However, text can be decorative, incomplete, fleeting or contradicted by the footage. A title card reading “camera settings” provides limited clarity if the rest of the video shows editing software without explaining the connection.
Spoken Language
Speech can state the subject, define relationships and explain steps that visuals cannot. Record the meaningful terms and propositions actually spoken, not a presumed transcript. Automatic transcription can omit words, mishear names and mishandle accents, music or overlapping speakers. Spoken language adds semantic context; it does not guarantee accurate transcription or a particular classification.
Captions and Hashtags
A caption can state the intended topic, add context and connect the video to a specific question. It is most useful when it accurately summarizes what the viewer receives. A caption does not prove that the footage delivers the promise or that viewers understood it.
Hashtags are labels, not magic instructions. Relevant tags can reinforce the topic or place it in a broader conversation. Broad, irrelevant or overused tags provide little diagnostic value. Repeating the same tag set across unrelated videos may create the appearance of consistency in metadata while the content itself remains inconsistent.
Evaluate each hashtag by asking: Does it accurately describe the entity, question, audience or context shown in this specific video? If not, remove it. No fixed hashtag count unlocks niche distribution.
Sound and Audio Context
Audio can serve several roles:
- Primary subject evidence: a musician demonstrates the sound being discussed.
- Supporting context: a trend sound frames the format or joke.
- Atmosphere: background music changes tone without defining the subject.
- Noise: the selected sound is unrelated to the information in the video.
A sound can provide cultural or trend context without defining the video’s main topic. Record its role instead of assuming that use of a popular sound assigns the post to one niche.
Creator, Series and Account Context
Previous posts, recurring formats, playlists and series labels can provide context for a new video. A “Part 4” label is clearer when the video also restates the specific subject; viewers may encounter an episode without seeing earlier parts.
Account history should not be treated as a permanent category. A creator can cover several related topic clusters—for example, home coffee equipment, brewing methods and ingredient science—while each video communicates its own subject clearly. Changing topics does not automatically confuse the algorithm, and no verified fixed number of posts is required for TikTok to “understand” an account.
Captions, Spoken Words, On-Screen Text and Hashtags
Semantic consistency means agreement in meaning, not identical wording. A well-aligned tutorial might show a stained shoe, say “remove salt marks from suede,” display “suede salt-stain removal,” and use a caption promising the same procedure. The words vary, but the entity and task remain stable.
Consistency does not require:
- repeating the same keyword unnaturally in speech, text and caption;
- adding the same hashtags to every post;
- publishing only one narrow subject forever;
- using a particular phrase a fixed number of times;
- assuming a creator has been assigned a permanent niche; or
- removing useful nuance merely to make all wording identical.
The test is conceptual: would each layer lead a careful reviewer toward the same primary entity and question? Synonyms, examples and supporting terms are useful when they clarify the relationship. Repetition without meaning is not semantic alignment.
Viewer Response and Search as Supporting Evidence
Search Queries and Search-Led Discovery
Search evidence begins with an active information need. TikTok says Creator Search Insights can show topics people search for and, where available, search analytics for posts inspired by those topics.[2] TikTok also says content-query match is generally more influential than other factors for most users in Search.[1]
If a video about “how to clean a cast-iron pan” receives discovery from a closely related query, that is evidence of alignment in a Search environment. It does not reveal the exact rule, field or internal label that produced the result. Search traffic without query detail is weaker evidence. The absence of Search traffic does not prove classification failure; demand, competition, eligibility, timing and reporting availability may also matter.
Comments as Audience Interpretation
Comments can reveal the topics viewers chose to discuss. Repeated questions about sizing on a fashion video may indicate that sizing became a salient audience interpretation. That evidence belongs to the viewer-response layer, not the creator-provided layer.
Comments can also be jokes, arguments, spam, copied phrases or off-topic reactions. Record recurring interpretations and contradictory themes, but do not treat comments as a direct window into TikTok’s internal classification. A full sentiment or topic-coding audit is a separate methodology; for this topic map, a concise record of recurring relevant interpretations is enough.
Engagement Patterns and Distribution Context
Likes, shares, saves, comments, watch behavior and follows are viewer actions. They may help describe audience response, but they do not fully explain why the recommendation system distributed the content. Strong engagement can coexist with unclear topic evidence: a confusing video may attract debate, surprise or humor.
For You and Search should also remain separate. For You traffic shows that views occurred in a personalized feed context. Search traffic shows query-led discovery. Neither source proves one specific topic signal, and neither is itself a niche score.
How to Build a Consistent Topic-Signal Map
The framework below is an analyst’s worksheet, not TikTok’s disclosed taxonomy. For each category, record the source, what it may indicate, what it cannot prove, how alignment will be judged and what should be measured next.
| Evidence category | What to record and where it comes from | What it may indicate | What it cannot prove | How to evaluate consistency | What to measure next |
|---|---|---|---|---|---|
| Primary subject evidence | Main entity, action and outcome visible in the published video | The subject a viewer can directly observe | An internal label, confidence score or ranking weight | Ask whether the central object or action matches the stated topic | Viewer interpretations and performance among comparable videos |
| Supporting attribute evidence | Features, steps, comparisons, problems and outcomes discussed | The aspect of the main entity the video addresses | That every supporting detail has equal importance | Check that details serve the primary question rather than create a competing topic | Where viewers ask for clarification or misidentify the focus |
| Spoken-language evidence | Manual transcript or verified spoken terms from the audio | Explicit semantic context, relationships and instructions | Perfect transcription or guaranteed classification | Compare speech with the entity, attribute and visual demonstration | Transcript errors, unclear terms and audience comprehension questions |
| Visual and on-screen evidence | Objects, actions, scenes, labels and meaningful overlay text | What the video depicts and names | That decorative text or a brief object defines the main topic | Review whether visuals reinforce or contradict the spoken promise | Opening clarity, demonstration sequence and contradictory objects |
| Caption and metadata evidence | Caption, relevant hashtags, language, series title and selected metadata | The creator’s declared topic and retrieval context | Viewer understanding, satisfaction or a guaranteed Search position | Check whether each label accurately describes the delivered content | Query match and performance after removing irrelevant labels |
| Audio or sound context | Sound title, speech, lyrics where relevant, music and its role | Subject matter, trend framing or atmosphere | That the sound alone defines the video’s topic | Classify the sound as primary, supporting, atmospheric or unrelated | Whether the concept remains clear without relying on trend knowledge |
| Search-intent evidence | Available search topics, surfaced queries, Search traffic and collection date | Discovery around a question or topic | The exact ranking rule, classification label or satisfaction | Compare the query’s entity and intent with the video’s actual answer | Matched query-led videos, viewing depth and follow-on actions |
| Audience-interpretation evidence | Recurring relevant comment themes and clear questions | How observable commenters interpreted the content | All viewers’ understanding or TikTok’s internal category | Look for recurrence, specificity and contradiction | A clearer follow-up and the same comment-review rule |
| Distribution context | For You, Search and other available traffic sources at a matched post age | Where reported views occurred | Why the system selected the video or which signal caused reach | Compare source counts and shares only under consistent definitions | Total views, source mix and audience response in the same window |
| Contradictory or noisy evidence | Irrelevant tags, mismatched visuals, ambiguous text, off-topic comments and trend noise | Where the subject may be unclear or multiple interpretations are plausible | That any mismatch necessarily harmed distribution | Identify which layer conflicts with the intended entity or question | One future test that removes the most material contradiction |
| Unavailable internal evidence | Hidden labels, embeddings, weights, candidate sets and model confidence | Nothing reliable without authorized access | Any creator-level claim about the secret formula | Mark unavailable rather than replacing it with a proxy | Observable content and audience evidence only |
Reusable Topic Evidence Map
Create one row per video. Do not add the fields into a universal niche score. High, medium and low alignment can be useful internal labels only when the team writes a rule for them and applies that rule consistently.
| Worksheet field | Entry guidance |
|---|---|
| Video identifier | Post URL, ID or stable internal name |
| Intended topic | One plain-language statement of the subject |
| Primary entity | Main person, object, process, place or concept |
| Primary attribute | Feature, action, comparison, problem or outcome |
| Audience question | The need the video is intended to answer |
| Search intent | Informational, comparative, navigational, transactional or another defined intent |
| Spoken topic terms | Verified relevant words and propositions actually spoken |
| On-screen text | Meaningful text exactly as shown |
| Caption language | Caption promise, entity and key contextual terms |
| Hashtags | Relevant tags plus a note for broad or questionable tags |
| Sound or audio relevance | Primary, supporting, atmospheric or unrelated, with a reason |
| Visible subject matter | Main objects, scenes, actions and demonstrated result |
| Content format | Tutorial, review, story, trend, comparison, demonstration or another format |
| Series or cluster | Related content group, if any |
| Search-query context | Available query or topic information, source and collection date |
| Search traffic | Displayed count or share at the defined post age, if available |
| For You traffic | Displayed count or share in the same reporting window, if available |
| Recurring comment topics | Relevant repeated interpretations under a documented review rule |
| Relevant engagement actions | Available watches, likes, comments, shares, saves or follows with definitions |
| Contradictory audience interpretations | Recurring readings that differ from the intended topic |
| Topic-evidence alignment | Aligned, missing or contradictory by layer, with a written rationale |
| Uncertainty | Missing data, ambiguous evidence and plausible alternatives |
| Comparison group | Videos matched by topic, format, duration, audience and post age |
| Confounding variables | Material differences in creative, timing, eligibility, promotion or external demand |
| Next content test | One semantic change and one defined outcome to review |
A Step-by-Step Topic Classification Audit
1. Define the Intended Topic
Write the main entity, primary attribute or question, and audience need before reviewing performance. “Running shoes” is a category. “How to choose trail-running shoes for wet ground” is an auditable topic.
2. Inventory the Content Evidence
Record the spoken terms, meaningful on-screen text, caption, relevant hashtags, role of the sound, visible objects, demonstrations and scenes. Use the published version rather than a script that may differ from the final edit.
3. Record Search and Discovery Context
Capture available Search queries, Search traffic, For You traffic and other source labels. Record the analytics surface, collection date, post age and whether a field is unavailable. Do not reconstruct unavailable query data from comments or guesses.
4. Review Audience Response
Note recurring comment interpretations and relevant engagement actions. Keep the claims narrow: comments show what observable commenters wrote; engagement shows recorded viewer actions. Neither source discloses a classification score.
5. Find Alignment, Missing Evidence and Contradictions
Mark each layer:
- Aligned: it supports the intended entity and question.
- Missing: the layer does not communicate useful subject information.
- Contradictory: it points toward a materially different subject or intent.
- Unavailable: the evidence cannot be observed from the accessible surface.
Missing is not automatically bad. A silent visual demonstration may not contain speech. The question is whether the remaining evidence communicates the subject clearly enough for the intended audience and format.
6. Choose Comparable Videos and a Reporting Window
Select a group of videos with similar topics, audience needs, formats, duration bands and organic or paid status. Compare them at the same post age or over the same complete period. A seven-day-old tutorial should not be compared with a six-month-old trend clip as if they had equal discovery opportunities.
No single reporting window is universally correct. Use the shortest consistent window that captures the decision you need to make, then extend it if Search-led discovery or later distribution is part of the question. State the start, end, time zone and collection date.
7. Record Confounding Variables
Document material differences in the opening, duration, edit, creator appearance, posting time, season, trend participation, eligibility, paid promotion, account events and outside traffic. Also record changes in demand and any missing analytics. These variables may explain performance differences without requiring a classification story.
8. Separate Observation From Interpretation
Write two columns. “Three of five recurring comment themes concern freezer storage” is an observation under a defined review method. “Viewers interpreted freezer storage as the main topic” is a plausible interpretation. “TikTok classified the video as freezer content” is not supported by those comments.
9. Convert the Finding Into One Content-Clarity Test
Choose one material ambiguity and change it in a future, comparable video. For example:
Hypothesis: For 30–45-second beginner gardening tutorials about repotting, stating the plant type and repotting problem in speech and on-screen text will produce more aligned search-query context and fewer recurring comments misidentifying the technique at day seven.
Keep the topic, format, length band, audience and reporting window as comparable as practical. Measure discovery and audience response separately. Even if the next video performs better, report the result as consistent with the hypothesis unless the design supports a causal conclusion.
Topic-Signal Examples and Decision Table
The examples below are hypothetical. They are not Tiksta research, TikTok benchmarks or proof of internal platform classification.
| Hypothetical example and observed evidence | Alignment or mismatch | Possible interpretation | What the evidence does not prove | Recommended content adjustment | What to measure next |
|---|---|---|---|---|---|
| Aligned tutorial: The speaker explains how to sharpen a kitchen knife; close-up visuals show the angle; on-screen text names each step; the caption promises the same tutorial. | Strong alignment across speech, visuals, text and caption | The video communicates one clear entity and task through several modes | That TikTok assigned a specific label, or that the video will rank or be widely distributed | Preserve the alignment and remove only redundant wording | Matched tutorial discovery, viewer questions and viewing depth |
| Caption–visual mismatch: The caption promises a budgeting method, but most footage is a desk makeover with no visible budget or explanation. | Caption and visual evidence conflict | The intended topic may be unclear to viewers reviewing the actual footage | That the mismatch caused weak reach or a particular internal classification | Show the budget steps and numbers, or rewrite the caption to match the makeover | Recurring comment interpretations and matched posts with aligned footage |
| Trend sound: A popular sound frames a joke about tax filing, while speech and text explain one deductible expense. | Sound supplies trend context; speech and text define the subject | The sound may help viewers recognize the format without carrying the full topic | That use of the sound places the video in a tax niche or causes distribution | Keep the sound subordinate and make the tax question explicit | Whether viewers and available search context identify the intended expense question |
| Different recurring comment topic: A video intends to explain camera lighting, but recurring comments focus on the microphone. | Audience interpretation diverges from the intended topic | The microphone may be more salient, or the lighting explanation may be unclear | That every viewer shared this interpretation or TikTok classified the post as audio content | Reduce microphone prominence and name the lighting problem early | Comment themes and topic clarity on the revised video |
| Query-led discovery: Available Search context shows discovery around “how to stop basil leaves curling,” closely matching the spoken question and demonstration. | Search intent and content evidence align | The video appears relevant in a query-led discovery environment | The exact ranking rule, internal label, satisfaction or future Search performance | Continue answering the specific question without stuffing the phrase | Matched query-led posts, search traffic and follow-on audience response |
| Broad hashtags: A detailed pottery repair video uses #fyp, #viral and #art but no accurate description of the repair shown. | Video evidence is specific; metadata evidence is broad | The hashtags add little diagnostic information about the actual topic | That broad tags necessarily reduce reach or block classification | Use only relevant descriptors and make the repair subject clear in the caption | Discovery context and audience interpretation across comparable repair videos |
| Related subtopics: A creator alternates between bread fermentation, shaping and oven technique, and each video clearly names its own question. | Different subtopics align within a wider baking cluster | The account can cover related needs without identical wording or hashtags | A permanent account category or a guaranteed cross-video recommendation relationship | Use clear series navigation while preserving video-level specificity | Performance within each subtopic and movement between related series |
| Strong engagement, unclear topic: A surprising clip earns many comments and shares, but the caption, sound and visuals point to different subjects. | Audience activity is strong; semantic evidence is noisy | The clip prompted action, perhaps because of surprise, debate or ambiguity | That viewers understood the intended topic or that engagement established a niche | Clarify the subject in the next comparable clip without removing the engaging premise | Coded comment themes, source mix and content clarity under the same window |
Limitations and Common Misinterpretations
The most common mistake when interpreting TikTok niche signals is collapsing observation, interpretation and internal causation into one claim. A creator observes that a video uses a hashtag and receives Search views, then concludes that the hashtag caused TikTok to classify and rank it. The evidence supports only the observed tag and discovery outcome. Several explanations remain possible.
Avoid these unsupported conclusions:
- Changing topics automatically confuses the algorithm.
- TikTok permanently categorizes an account after a fixed number of posts.
- Using one exact keyword a certain number of times guarantees classification.
- A specific hashtag count unlocks niche distribution.
- Strong engagement proves that the system understood the intended topic.
- Comments reveal the platform’s internal topic label.
- For You distribution identifies the signal that caused a recommendation.
- No Search traffic means classification failed.
- One successful post establishes a stable account-level niche.
Every available source has limits. Published content shows what was communicated, not how every viewer or model processed it. Creator analytics aggregate outcomes and may omit individual journeys. Comments represent people who chose to comment and remained visible. Search data may be partial or unavailable. Public documentation describes examples of factors, not a complete model. Academic multimodal research can inform terminology without revealing TikTok’s implementation.
If a team uses an optional internal alignment score, label it as a custom editorial tool. Publish its categories, assumptions and missing-data rules. Use it only to apply the team’s review consistently. Do not imply that TikTok uses the same scale or weights.
What to Measure Next
A useful topic-classification review ends with a constrained statement and a future test:
“For [video or cohort], we observed [aligned, missing and contradictory evidence] from [named sources] during [reporting window]. This is consistent with [possible interpretation], but [alternatives and missing data] remain. We will change [one semantic feature] and compare [defined discovery and audience measures] among [matched videos] at [the same post age].”
Prioritize the next measurement by the largest uncertainty. If viewers repeatedly misidentify the topic, test clearer speech or visuals. If the content is clear but query relevance is uncertain, review available Search context. If engagement is strong but the reason is unclear, inspect audience interpretations without treating them as internal labels. If the cohort is inconsistent, improve the comparison before changing the content.
The purpose of this method is not to reverse-engineer a secret TikTok niche algorithm. It is to make the intended subject clearer, preserve the boundary between evidence and inference, and build better content tests from observations creators can actually verify.
Sources
- TikTok Help Center: How TikTok Recommends Content. Supports the descriptions of user interactions, content information and user information; examples for For You and Search; and TikTok’s statement that factor importance can vary over time. Reviewed October 13, 2026.
- TikTok Help Center: Creator Search Insights. Supports the description of search-topic exploration and post search analytics where available. Reviewed October 13, 2026.
- Wang et al.: Truly Multi-modal YouTube-8M Video Classification with Video, Audio, and Text. Supports the general statement that video-classification research can combine visual, audio and text features; it is not evidence of TikTok’s implementation. Reviewed October 13, 2026.