TikTok Comment Sentiment Audit: A Practical Coding Framework for Creators
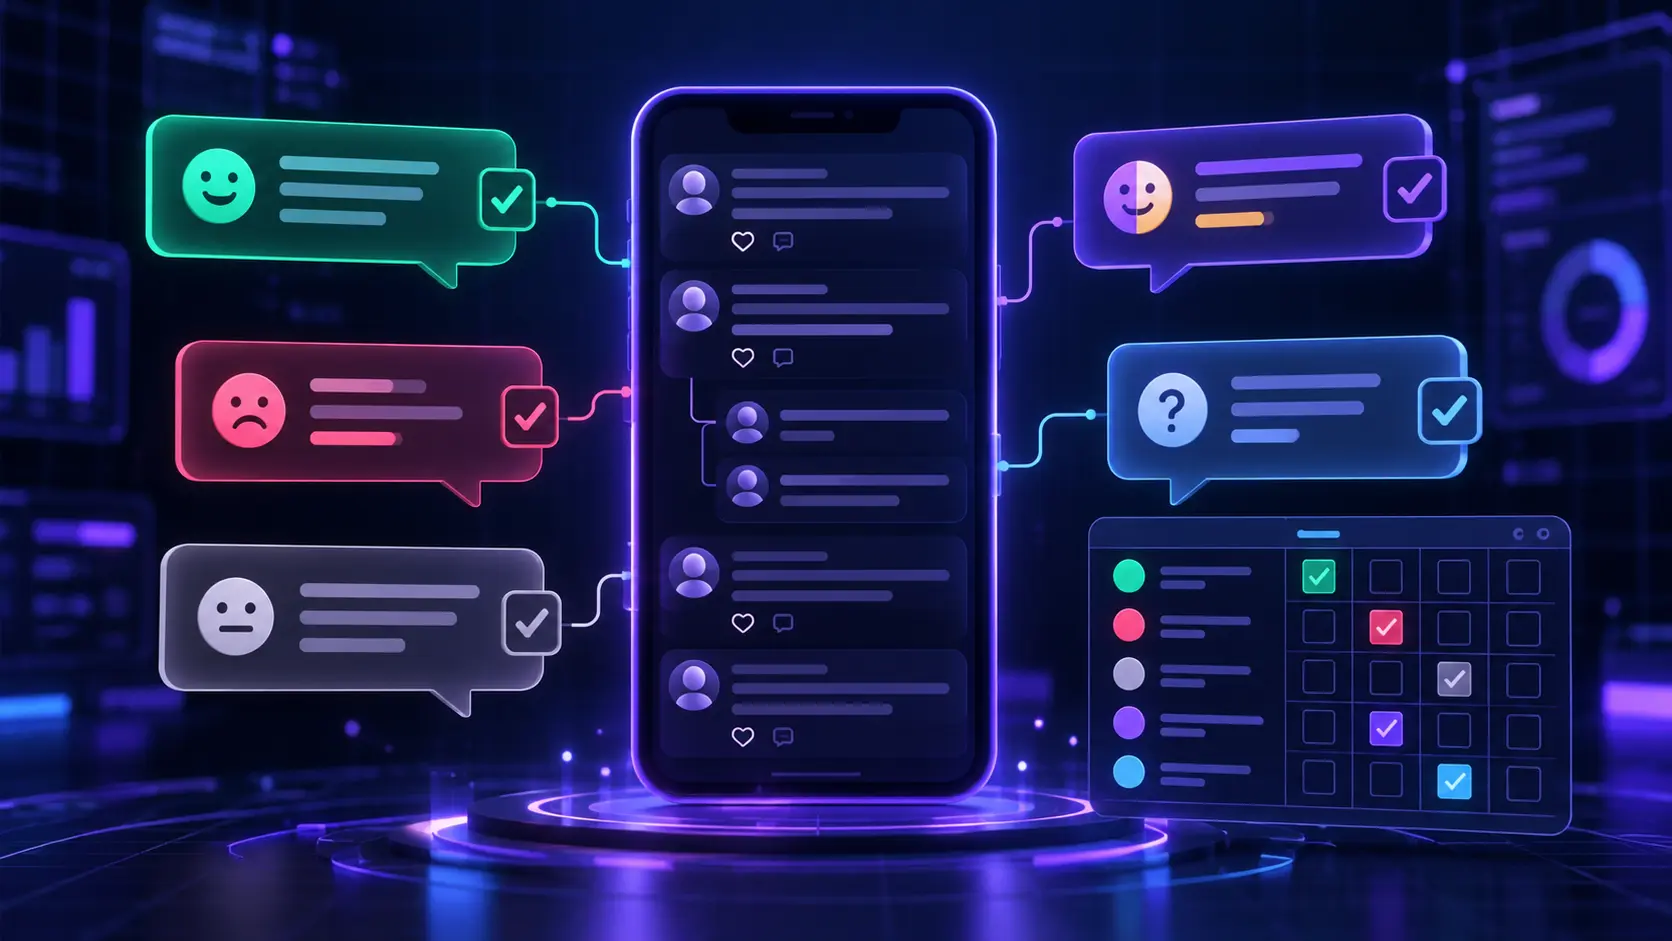
A TikTok comment sentiment audit is a structured review of what a documented sample of comments expresses. It does not ask only how many comments a video received. It asks whether those comments show approval, criticism, confusion, curiosity, purchase intent, requests for more detail or another response that matters to the creator.
The practical method is to select a traceable sample, code each comment for sentiment and topic, record uncertainty, and compare like with like. The result is not a universal verdict on the audience. It is a transparent reading of a defined set of comments within a stated time window.
This focus keeps the audit distinct from broader explanations of TikTok engagement actions. Likes, comments, shares and saves provide useful context, but this audit concentrates on the meaning inside comments and replies.
What Is a TikTok Comment Sentiment Audit?
A sentiment audit assigns a consistent label to the emotional or evaluative position expressed in each sampled comment. A topic audit labels what the comment is about. The two codes answer different questions:
- Sentiment coding: How does the commenter appear to respond?
- Topic coding: What subject, need or issue does the commenter raise?
“Love this, but the setup step is confusing” is a simple example. Its sentiment is mixed: praise and friction appear together. Its topic might be “setup instructions.” Reducing it to positive because it begins with praise would discard useful information.
Comment volume alone cannot reveal this response quality. Two videos can each receive 500 comments while producing very different conversations. One may attract specific questions and peer-to-peer replies; the other may contain short reactions, duplicated phrases or an argument unrelated to the video. Volume measures activity. Coding examines what the activity expresses.
That distinction also separates this audit from the comment-to-view ratio. The ratio measures comment quantity relative to views as a conversation-depth indicator. Sentiment and topic coding analyze the content of a sampled set of comments. Neither method substitutes for the other.
How Sentiment and Topic Coding Work
Start with One Decision Question
Define the decision the audit should support before collecting comments. A useful question is narrow enough to influence an action, such as:
- Which parts of a tutorial create the most confusion?
- Do comments on a new series express demand for another episode?
- What objections appear after a product explanation?
- Are negative reactions about the topic, the presentation or a factual claim?
- Do reply chains contain deeper questions than isolated top-level comments?
Avoid a vague question such as “What does my audience think?” It invites a codebook so broad that almost any interpretation can fit.
Write the question at the top of the audit sheet. Then specify the unit of analysis. For most creator audits, one visible comment or reply equals one coding unit. If meaning depends on a thread, preserve the full thread identifier and parent-comment context even though each comment occupies its own row.
Sentiment Codes Describe Position
A workable sentiment scheme should allow uncertainty instead of forcing every comment into positive, neutral or negative.
| Sentiment code | Operational definition | Include | Do not assume |
|---|---|---|---|
| Positive | Clear approval, satisfaction, gratitude or support | Direct praise; an approving emoji with clear context | That every enthusiastic phrase supports every claim in the video |
| Negative | Clear criticism, dissatisfaction, rejection or frustration | A specific complaint; an unambiguous negative reaction | The reason for the reaction unless the comment states it |
| Neutral or informational | Little or no evaluative position | A factual question, tag or clarification without a clear stance | That a question implies criticism |
| Mixed | More than one clear sentiment appears | Praise paired with a complaint; excitement plus concern | Which side is stronger unless a separate rule defines intensity |
| Unclear | Sentiment cannot be assigned confidently | Ambiguous slang, uncertain sarcasm, missing context or an unfamiliar reference | A forced positive or negative label |
If the audit question requires more detail, add a separate intensity field rather than multiplying sentiment categories. Keep “unclear” as a valid analytical result.
Topic Codes Describe Subject Matter
Topic categories should follow the research objective, not a generic list used for every account. A tutorial audit might include “instructions,” “tools,” “cost,” “result,” “troubleshooting” and “next tutorial request.” A product explainer might use “features,” “price,” “availability,” “use case,” “comparison” and “trust concern.”
Define each topic with:
- A short label.
- A one-sentence definition.
- Inclusion criteria.
- Exclusion criteria.
- At least one hypothetical example.
- A rule for overlap with neighboring topics.
Choose whether topics are single-label or multi-label. A single primary topic makes distributions easy to interpret and sum to 100%. Multi-label coding preserves comments that raise several issues, but topic percentages can then total more than 100%. State the choice before coding.
Treat Difficult Language as Data, Not Noise
Sarcasm, slang, emojis and cultural references often require context. Read the comment with the video, caption and nearby thread when available. Do not infer tone from one emoji or punctuation mark alone.
Use these rules for difficult cases:
- Mixed sentiment: Assign “mixed” and identify the topic behind each component in the rationale.
- Sarcasm: Code the intended sentiment only when context makes it sufficiently clear; otherwise use “unclear.”
- Slang and emojis: Record the literal expression in an anonymized excerpt and explain the contextual reading. If the meaning is unfamiliar, do not guess.
- Multiple languages: Use a fluent coder or a documented translation process. Record the source language and lower confidence when nuance may have been lost.
- Missing context: Mark the case unclear or unavailable. Do not reconstruct deleted parent comments from assumptions.
- Multiple topics: Apply the declared primary-topic rule or use multiple topic fields consistently.
TikTok offers AI-based comment insights[1] that summarize and filter comments into categories. Those summaries can help locate possible themes, but they are not a substitute for checking sampled comments. Automated classification can miss sarcasm, mixed reactions, evolving slang, multilingual nuance and thread context.
How to Build a Practical Comment Codebook
A codebook combines the category definitions with a row-level audit log. It should make another reviewer able to understand what was observed, which code was assigned, why it was assigned and what remains uncertain.
Required Data Fields
| Field | What to record |
|---|---|
| Comment identifier | A stable internal ID; avoid publishing usernames or personal details |
| Video identifier | Video URL, post ID or an internal video code |
| Publication or collection date | State which date is recorded and use it consistently |
| Comment text or anonymized excerpt | The text needed to support the code, with personal information removed |
| Sentiment code | One category from the defined sentiment scheme |
| Topic code | The primary topic or declared multi-label topics |
| Reply or top-level status | Top-level comment, audience reply or creator reply |
| Thread and parent identifier | The chain needed to reconstruct context without exposing personal data |
| Confidence level | High, medium or low under written criteria |
| Unclear or mixed flag | A visible flag that can be filtered for review |
| Coding rationale | A short explanation tied to words or context in the comment |
| Recommended response | A possible content, reply, moderation or research action |
| Coder and review status | Original coder, second-pass status and any final decision |
Define confidence in operational terms. For example, high may require explicit wording and sufficient context; medium may indicate a plausible code with some contextual ambiguity; low may indicate that slang, sarcasm, translation or missing thread context materially affects the reading. Confidence is about the code, not the importance of the comment.
Select a Sample That Matches the Question
Choose videos because they can answer the audit question, not because they are simply the best or worst performers. Suitable designs include:
- A census of all eligible comments on one low-volume video.
- A sample from several videos in the same series.
- Equal-sized samples from two comparable formats.
- A sample from the same post age, such as each video's first seven days.
- Separate strata for top-level comments and replies.
Use consistent reporting windows. Comparing the first 24 hours of one video with the lifetime comments of another confounds response pattern with exposure time. For older and newer videos, use the same post-age window whenever possible.
The order shown in the interface is also part of the sampling method. “Top” or highly ranked comments are not equivalent to all comments; ranking may overexpose early, popular or reply-generating contributions. Pinned comments are selected by the creator and should be flagged rather than treated as randomly prominent. Record whether the sample came from top-ranked, newest-first, a systematic interval, a complete export or another route.
TikTok allows creators to limit who can comment and to filter all comments, unwanted comments or comments containing selected keywords. Filtered comments can be reviewed and approved or deleted, according to TikTok's comment-management documentation[2]. These settings alter what is visible for sampling. Record active filters, moderation practices and whether the reviewer had access to filtered queues.
Deleted, filtered or otherwise unavailable comments create missing data. Report how many were known to be unavailable when that information exists. Do not assign them a sentiment or assume they were negative. If a parent comment is missing, flag dependent replies as context-limited.
Set Inclusion and Exclusion Rules Before Coding
Typical inclusion rules might admit audience comments posted within the chosen window, in the target language set, on the selected videos. Exclusion rules might remove the creator's own replies, exact duplicates, obvious bot spam, comments outside the window or comments whose only content is a tag when tags cannot answer the research question.
Keep an exclusion log by reason. If 40 duplicate comments are removed, the reader should know that duplication occurred even though those rows are not part of the sentiment denominator.
If a video received incentivized or purchased comments, separate or exclude them from any organic-audience interpretation. A service such as Tiksta's TikTok comments service may be relevant to a campaign operations record, but purchased comments are not evidence of genuine sentiment, reliable topic demand, community quality or organic distribution.
Use Sample-Size Ranges as Workload Guidance
No fixed number guarantees a representative TikTok comment sample. The appropriate scope depends on total eligible comments, the decision question, conversation diversity, comparison design and available coding time.
The following ranges are practical planning heuristics, not statistical guarantees:
| Eligible comment pool | Practical starting approach | When to expand or change it |
|---|---|---|
| Up to about 100 | Code all eligible comments when feasible | Sample only if privacy, language or time constraints make a census impractical |
| About 101–1,000 | Begin with a documented, stratified sample of roughly 100–250 | Expand if important groups are thin, topics remain unstable or unclear cases cluster |
| More than 1,000 | Begin with roughly 200–500 distributed across relevant videos, time bands, thread levels or other strata | Add rows where conversation diversity is high; do not increase only the easiest stratum |
For a comparison, allocate enough comments to each group to make the contrast interpretable. Equal targets can help when eligible pools differ greatly, while proportional targets better reflect the pool composition. Choose one logic and disclose it. If one group has very few eligible comments, code all of them and describe the comparison as directional rather than masking the imbalance with percentages.
Always disclose:
- Total available eligible comments.
- Number of comments coded.
- Selection method and sorting order.
- Videos and strata included.
- Reporting window and collection date.
- Exclusions and unavailable comments.
Time a pilot batch before committing to a final sample. Complex multilingual reply chains take longer than short, explicit top-level reactions.
A Step-by-Step TikTok Comment Audit
1. Define the Audit Question
Write one decision question, the intended use and the unit of analysis. Specify whether the output will guide a follow-up video, a community response, a moderation change or a research decision.
2. Choose Videos and the Reporting Window
Select videos that create a valid comparison or collectively answer the question. Use a consistent post-age or calendar window and record the collection date.
3. Select a Documented Comment Sample
Record the eligible pool, target sample, selection method, sorting order and any strata. A reproducible systematic sample, such as every nth eligible comment after a documented starting point, is usually stronger than choosing comments that look interesting.
4. Set Inclusion and Exclusion Rules
Decide how to handle creator replies, tags, duplicates, spam, off-topic comments, inaccessible comments, languages and comments outside the window. Apply the same rules across comparison groups.
5. Create the Sentiment and Topic Codebook
Define each code, include and exclude criteria, overlap rules and examples. Decide whether topics are primary-only or multi-label. Add confidence and uncertainty fields.
6. Test the Codebook on a Pilot Batch
Code a small, varied batch before the full sample. A pilot of about 20–30 comments often reveals overlapping categories, missing topics and unclear confidence rules. Include replies and difficult cases rather than testing only obvious comments.
7. Revise Unclear Category Definitions
Merge categories that coders cannot distinguish reliably. Split categories only when the distinction changes a decision. Record changes and recode the pilot so early rows follow the final rules. Practical qualitative guidance also treats codebook development as iterative and recommends discussing discrepancies and refining definitions before proceeding at scale.[3]
8. Code the Full Sample Consistently
Work from the documented sample list. Record the observed comment before adding the code, rationale or response idea. Avoid changing definitions silently halfway through.
9. Review Mixed, Uncertain and Disputed Cases
Filter all low-confidence, mixed and unclear rows. Reopen the video or thread when possible. Preserve the uncertainty flag even if a final working code is selected.
10. Calculate Distributions with the Sampled Comments as the Denominator
For a mutually exclusive category:
Category share (%) = comments assigned to the category ÷ all coded eligible comments in that sample × 100
If 120 eligible comments were coded and 30 received a negative sentiment code, the negative share is 30 ÷ 120 × 100 = 25%. This hypothetical calculation describes the coded sample, not every viewer or every person who saw the video.
Use the denominator 120 coded eligible comments, not total views, total visible comments or all comments ever received. Excluded and unavailable comments should be reported separately. If topics are multi-label, state that a comment can contribute to more than one topic and that topic shares may exceed 100% in total.
11. Compare Relevant Videos or Time Periods
Compare the same code definitions, selection logic and time window. Show both counts and shares because a large percentage based on a small group can mislead. Review notable differences against the actual comments before assigning a cause.
12. Record Limitations and Confounders
Maintain a confounder record for video age, reach, topic, format, call to action, creator replies, pinned comments, comment ranking, moderation settings, paid promotion, incentives, language mix, news events and traffic from outside TikTok. A confounder is a competing explanation, not an inconvenience to omit.
13. Translate Themes into a Measurable Response
Choose an action tied to the evidence: clarify one step, answer a recurring objection, produce a follow-up, update moderation guidance or ask a more precise question in the next video. Define what will be checked afterward and over what period.
Comment Coding Example
All comments below are hypothetical and contain no private personal information.
| Observed comment | Assigned sentiment code | Assigned topic code | Confidence | Analyst interpretation and limit | Possible response |
|---|---|---|---|---|---|
| “Finally, a version I can follow. Could you show the export settings next?” | Positive | Next tutorial request | High | Clear approval plus a request; it does not prove the whole audience wants a sequel | Make or test a short follow-up on export settings |
| “Great, another ‘easy’ method that needs three paid apps 🙃” | Negative | Cost or tool access | Medium | Likely sarcasm based on wording and emoji; intent should be checked against video context | Clarify which tools are optional and disclose costs earlier |
| “Does this work on Android?” | Neutral or informational | Compatibility | High | A direct question with no clear positive or negative position | Reply with platform requirements or test an Android version |
| “The result looks good, but step two lost me.” | Mixed | Instructions | High | Approval and confusion coexist; collapsing to positive would hide friction | Re-edit or answer step two with a close-up demonstration |
| “Sure 😭” | Unclear | Unclear | Low | Too little context to distinguish agreement, disbelief or an inside reference | Do not build a content decision from this row alone |
| Reply: “I tried it after the pinned fix and it works now.” | Positive | Troubleshooting resolution | High | Meaning depends on the reply chain and pinned fix; not an isolated reaction | Preserve the fix in a FAQ or follow-up caption |
The four layers should remain separate:
- Observed comment: What the person actually wrote, anonymized where necessary.
- Assigned code: The category applied under the codebook.
- Analyst interpretation: What the coded comment may indicate, with a stated limit.
- Recommended action: A testable response, not a claim that the interpretation is certain.
How to Handle Disagreement and Uncertainty
When Multiple Coders Are Available
Have coders independently label the same pilot batch. For each disagreement:
- Preserve both original codes.
- Compare the definition each coder applied.
- Discuss whether the disagreement comes from an unclear category, missing context or a genuinely ambiguous comment.
- Revise the codebook if the rule is inadequate.
- Record the final working code and the reason for the decision.
- Keep an unresolved or uncertainty flag when ambiguity remains.
The goal is a traceable decision, not forced unanimity. Do not invent an inter-rater reliability score. If the project requires a formal agreement statistic, choose and justify it before coding, ensure the design supports it and report the actual calculation and assumptions.
When One Creator Codes Alone
A solo auditor can still test consistency:
- Finish the pilot and freeze the first version of the codebook.
- Code the full sample without revisiting earlier decisions after every difficult row.
- Wait until a separate review session, then recode all low-confidence cases and a systematic subset of clear cases without looking at the original codes.
- Compare the first and second passes.
- Investigate repeated shifts, revise the relevant definition and recode all affected rows.
- Document that this was a within-coder consistency review, not independent validation.
This second pass cannot remove the analyst's perspective, but it makes drift visible.
Limitations and Common Misinterpretations
The most common TikTok comment sentiment analysis mistake is to treat whichever comments are easiest to see as a representative verdict from the audience. A top-ranked screen, a handful of memorable complaints or an automated summary may be useful for discovery, but none automatically represents all commenters, viewers or followers.
Other common errors include:
- Using the wrong denominator: Dividing categories by total views instead of coded eligible comments.
- Ignoring selection bias: Sampling only pinned, highly ranked or newest comments without naming that choice.
- Equating frequency with importance: A rare safety issue may require action even when a common joke dominates the count.
- Forcing ambiguity: Coding sarcasm, emoji-only responses or missing-context replies as certain.
- Mixing units: Treating a reply chain as one comment in some rows and several comments in others.
- Changing definitions midstream: Adding a code without revisiting earlier rows.
- Claiming causation: Assuming a topic or format caused sentiment without considering confounders.
- Generalizing beyond the sample: Presenting a directional audit as the opinion of every viewer.
- Treating automated labels as ground truth: Accepting AI categories without reading the underlying comments.
The audit is also shaped by platform visibility and moderation. Deleted comments cannot be coded. Filter settings can hide part of the conversation. Ranked comments are not a neutral ordering. Multilingual comments may lose nuance in translation. A rigorous report keeps these limits next to the findings.
How to Turn Findings Into a Content Response Loop
Comment coding becomes useful when it leads to a response that can be evaluated.
Connect Comments to Wider Community Context
Use other signals as context, not as substitute sentiment labels:
- Likes can show broad lightweight approval, but they do not explain why someone reacted.
- Shares can suggest that viewers found a video worth passing on, but not whether their reason was praise, criticism or debate.
- Saves can add context for instructional or reference value without revealing the saved viewer's opinion.
- Replies reveal whether a comment starts a conversation and whether questions receive peer or creator responses.
- Returning viewers, when available in account or video analytics, help show whether recurring comment themes appear alongside repeat audience behavior.
Do not infer that a person who commented is the same person counted in an aggregate returning-viewer metric. Compare patterns at the video, series or time-window level. A video with recurring troubleshooting topics, substantive reply chains and stronger returning-viewer context may warrant a deeper tutorial. It does not prove that the comments caused viewers to return.
Build the Response Loop
Use a six-part loop:
- Find a recurring theme. Identify a topic supported by coded rows, not one vivid anecdote.
- Check sentiment and confidence. Separate clear frustration from neutral questions and review uncertain cases.
- Inspect thread depth. Determine whether the theme appears in isolated comments or develops across replies.
- Choose one response. Create a follow-up video, revise an explanation, reply to a thread or adjust moderation.
- Define the next measurement. Reuse the same code definitions and set a comparable time window.
- Review the outcome. Check whether the target topic, sentiment pattern or unresolved-question share changed, while recording new confounders.
For example, an audit may find that “setup instructions” is a recurring topic and that many of those rows are neutral questions rather than negative reactions. The response should be a clearer setup demonstration, not a defensive video about criticism. After publication, audit the first seven days of eligible comments on the original and revised videos using the same sampling logic. Compare the relevant topic share, the mix of sentiment codes and the number of unresolved reply chains. Keep differences in reach, format and audience source in the confounder record.
A useful final audit statement is precise: “We coded 180 of 742 eligible comments from six tutorial videos, collected during each video's first seven days, using a stratified systematic sample across videos and top-level comments versus replies.” It should then report category counts and shares, unclear cases, exclusions, coding process, limitations and the action chosen.
That level of documentation turns comment reading into a repeatable research practice without pretending that human or automated coding can remove ambiguity from every TikTok conversation.
Sources
TikTok Support. “Comment insights on TikTok.” Documentation reviewed October 4, 2026.
TikTok Support. “Manage comments.” Documentation reviewed October 4, 2026.
The BMJ. “Practical thematic analysis: a guide for multidisciplinary health services research teams engaging in qualitative analysis.” Published 2023; reviewed October 4, 2026.